Publications
Peer-reviewed work on second-order and variance-reduced optimization for large-scale machine learning.
Journal articles
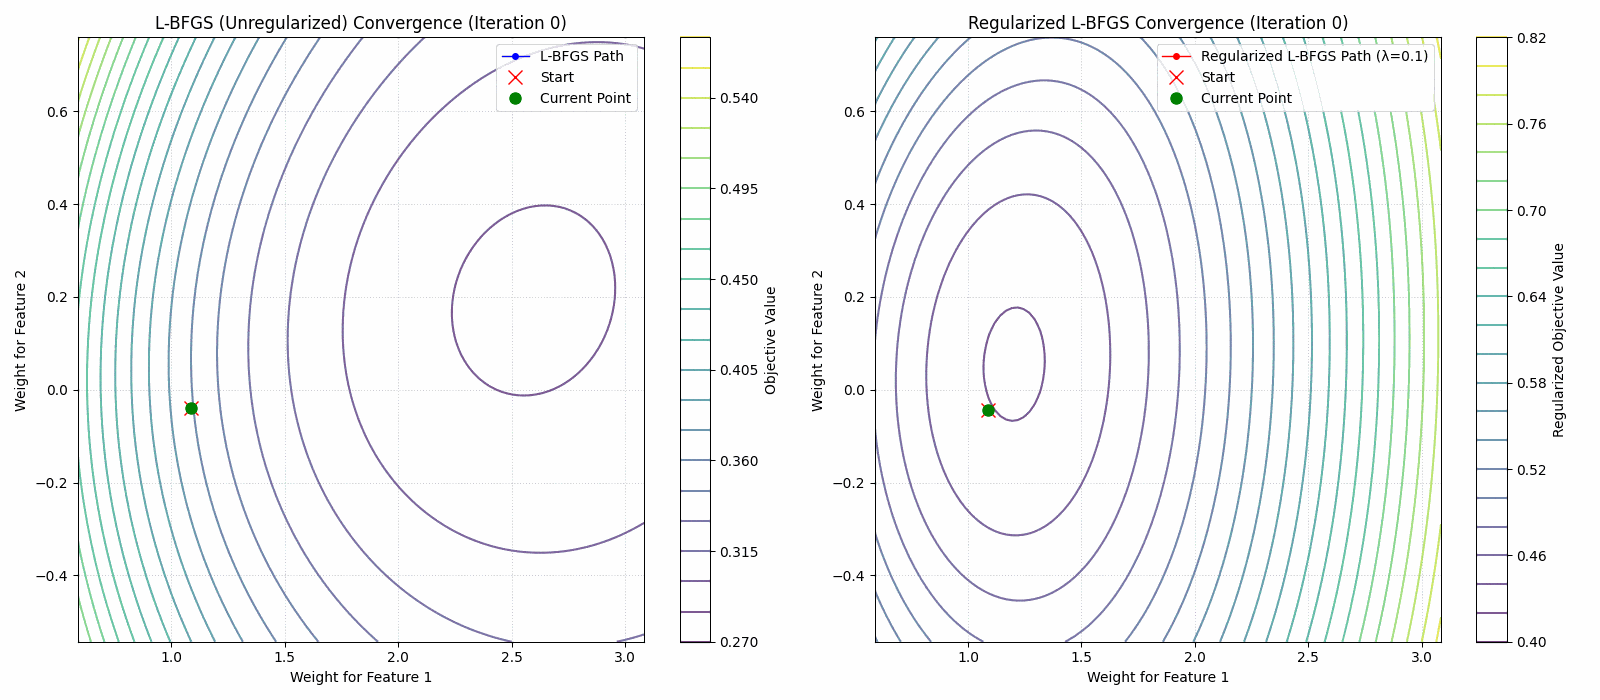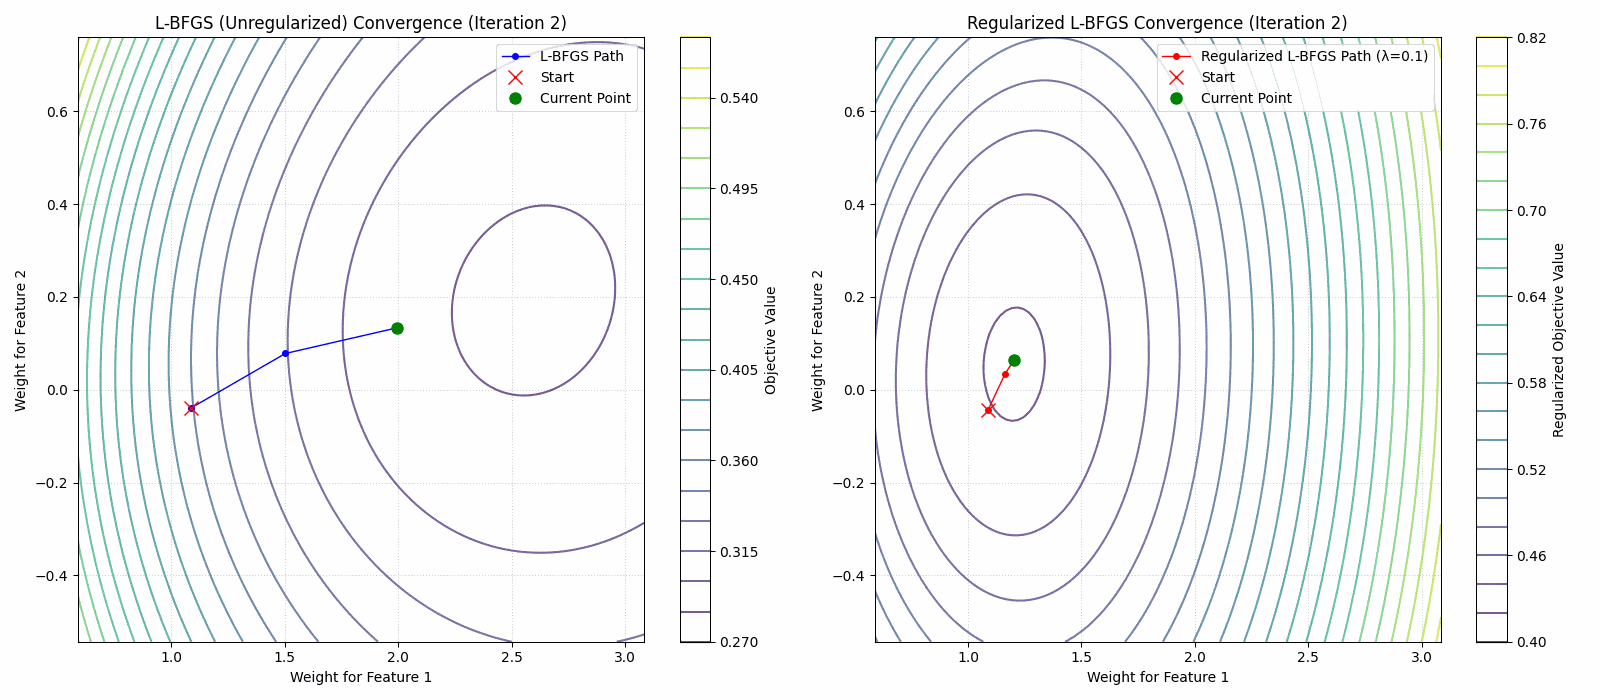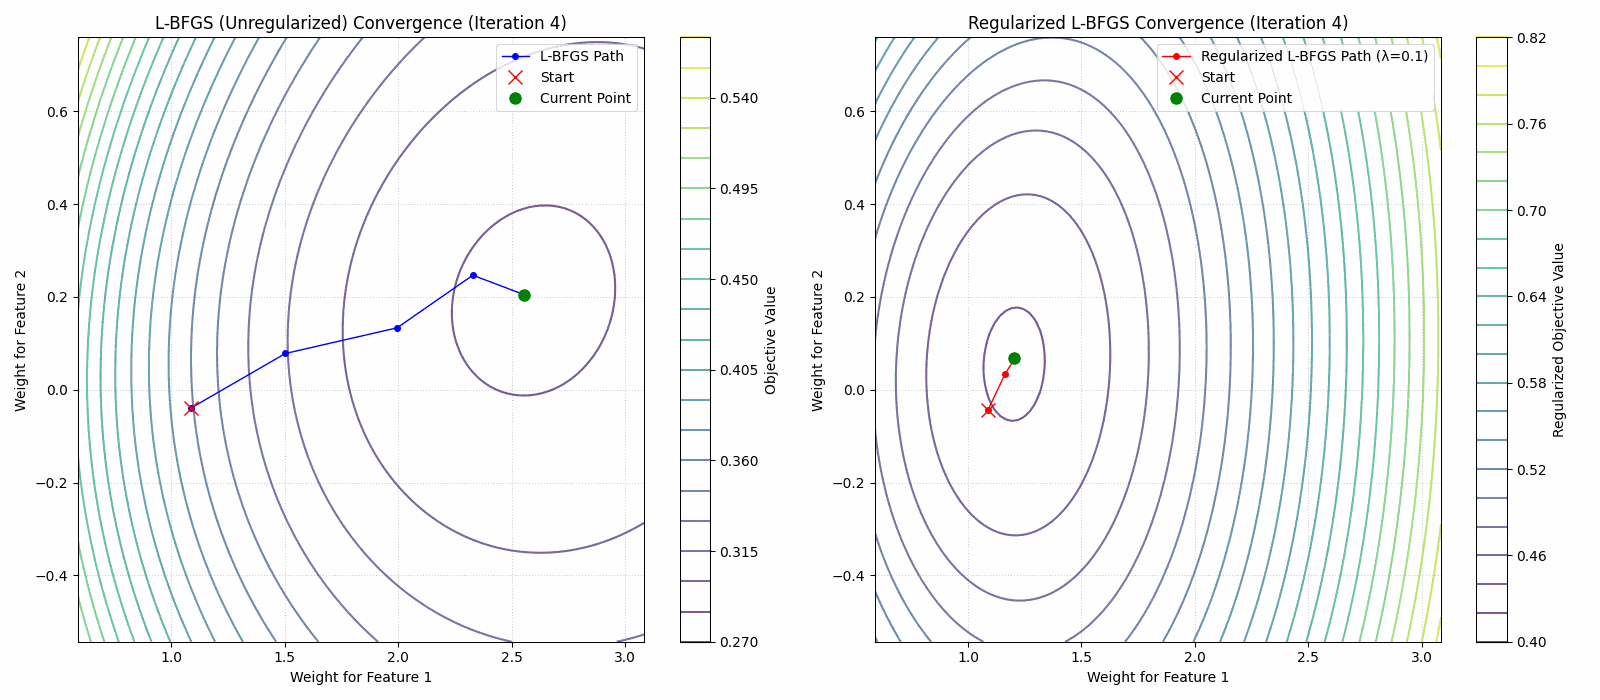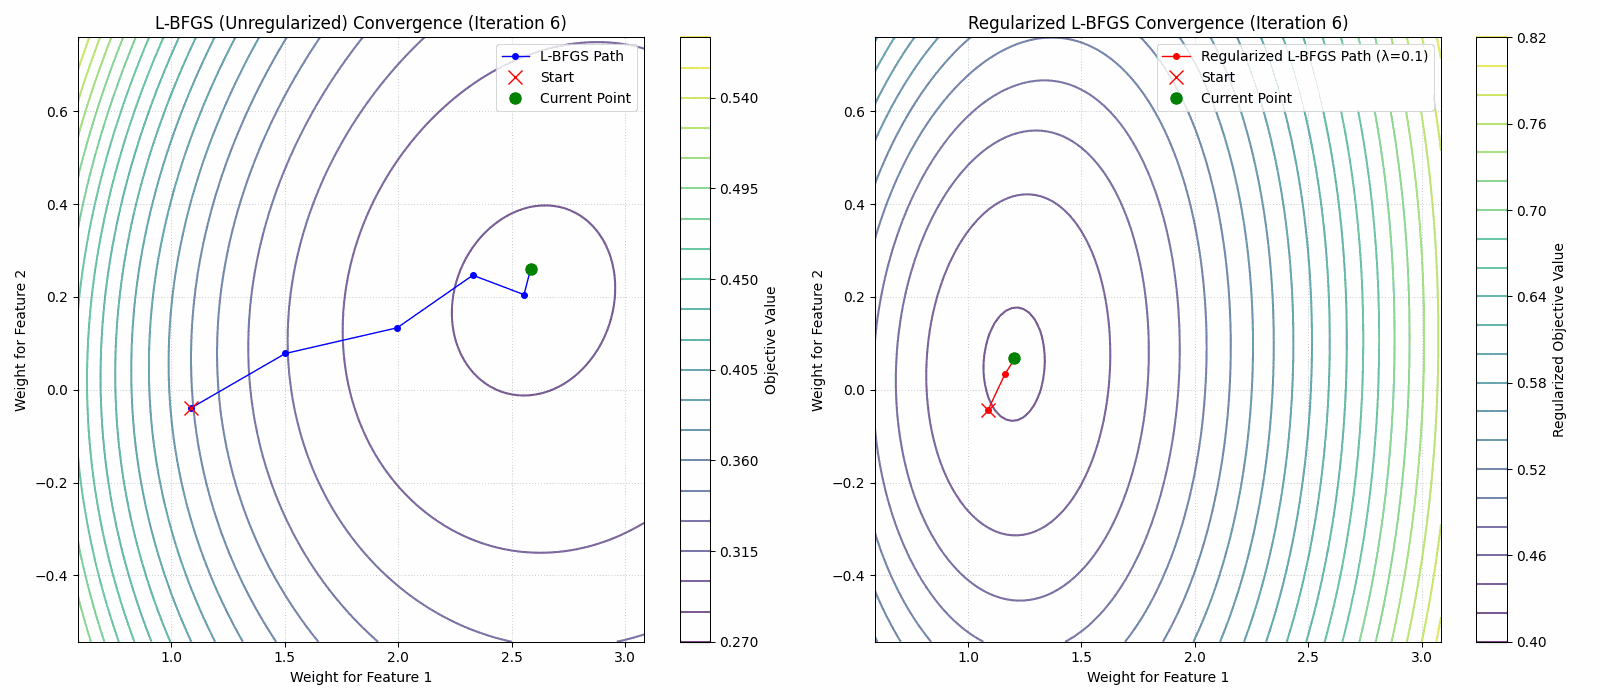
- A regularized limited memory BFGS method for large-scale unconstrained optimization and its efficient implementationsComputational Optimization and Applications, 2022The limited memory BFGS (L-BFGS) method is one of the popular methods for solving large-scale unconstrained optimization. Since the standard L-BFGS method uses a line search to guarantee its global convergence, it sometimes requires a large number of function evaluations. To overcome the difficulty, we propose a new L-BFGS with a certain regularization technique. We show its global convergence under the usual assumptions. In order to make the method more robust and efficient, we also extend it with several techniques such as the nonmonotone technique and simultaneous use of the Wolfe line search. Finally, we present some numerical results for test problems in CUTEst, which show that the proposed method is robust in terms of solving more problems.
- JIMO
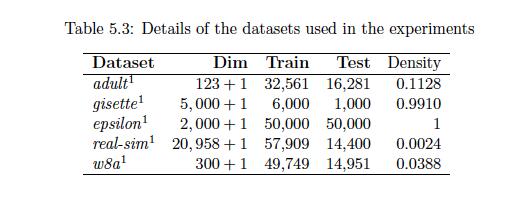 A stochastic variance reduced gradient using Barzilai-Borwein techniques as second order informationJournal of Industrial and Management Optimization, 2024In this paper, we consider to improve the stochastic variance reduced gradient (SVRG) method via incorporating the curvature information of the objective function. We propose to reduce the variance of stochastic gradients using the computationally efficient Barzilai-Borwein (BB) method by incorporating it into the SVRG. We also incorporate a BB-step size as its variant. We prove its linear convergence theorem that works not only for the proposed method but also for the other existing variants of SVRG with second-order information. We conduct the numerical experiments on the benchmark datasets and show that the proposed method with constant step size performs better than the existing variance reduced methods for some test problems.
Conference papers
- IJCNN
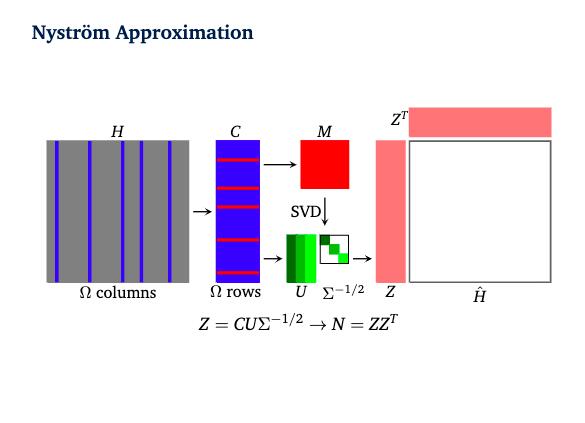
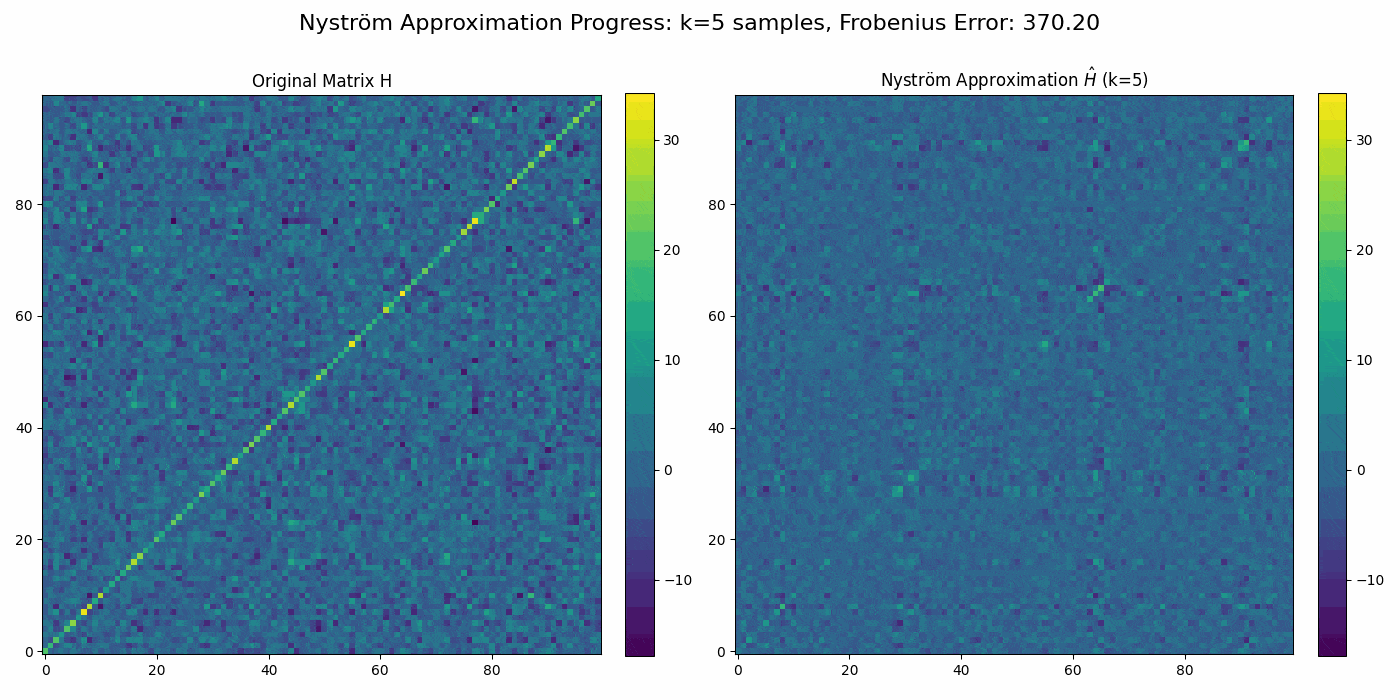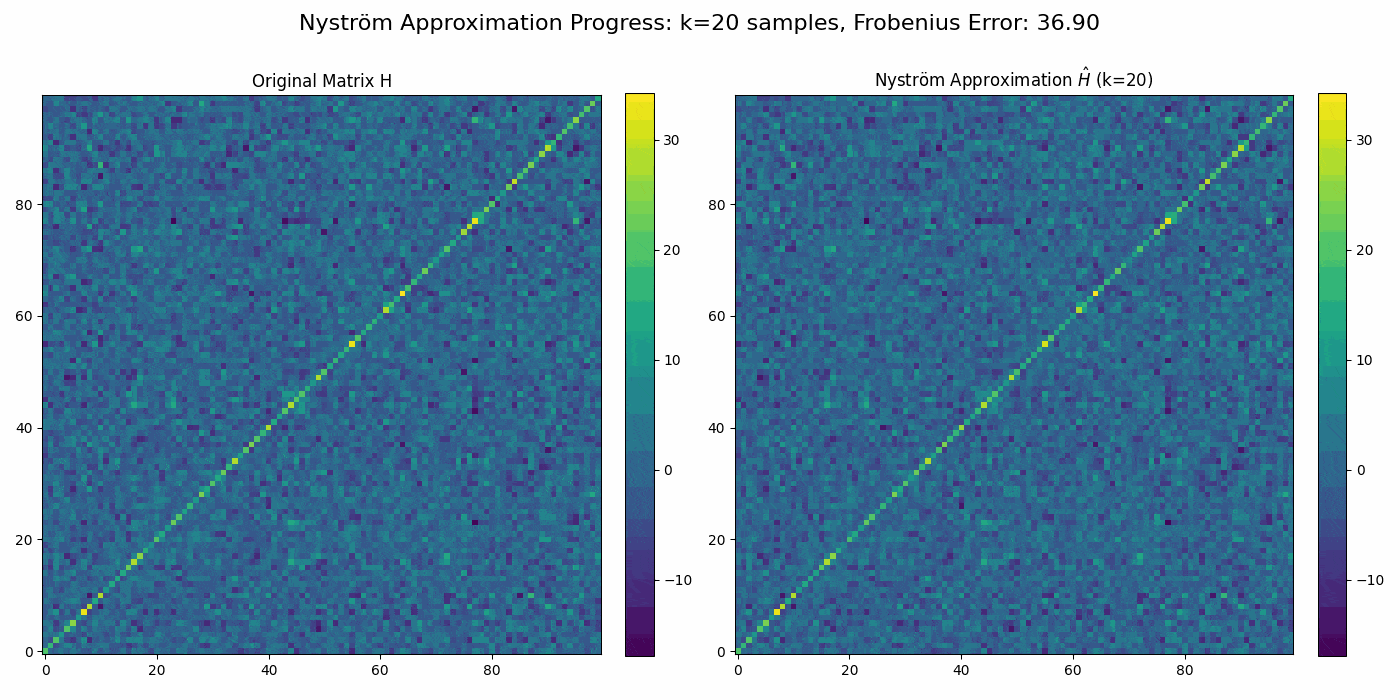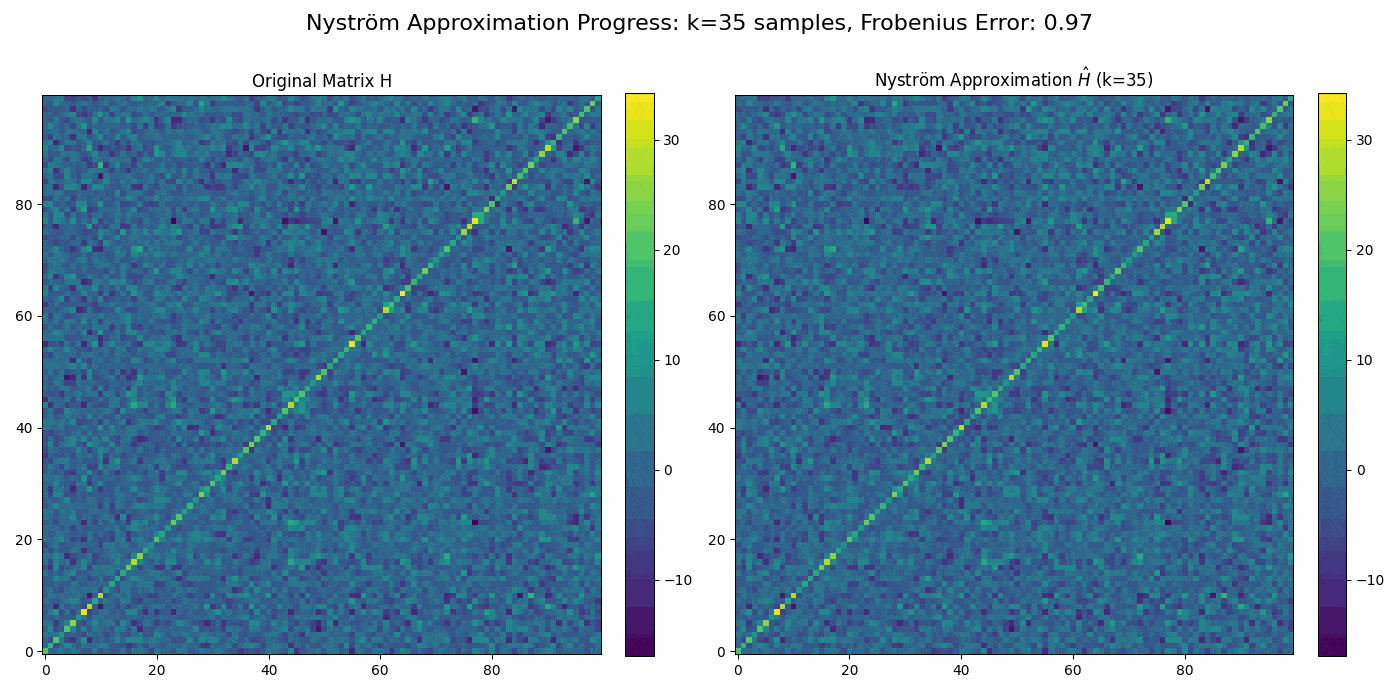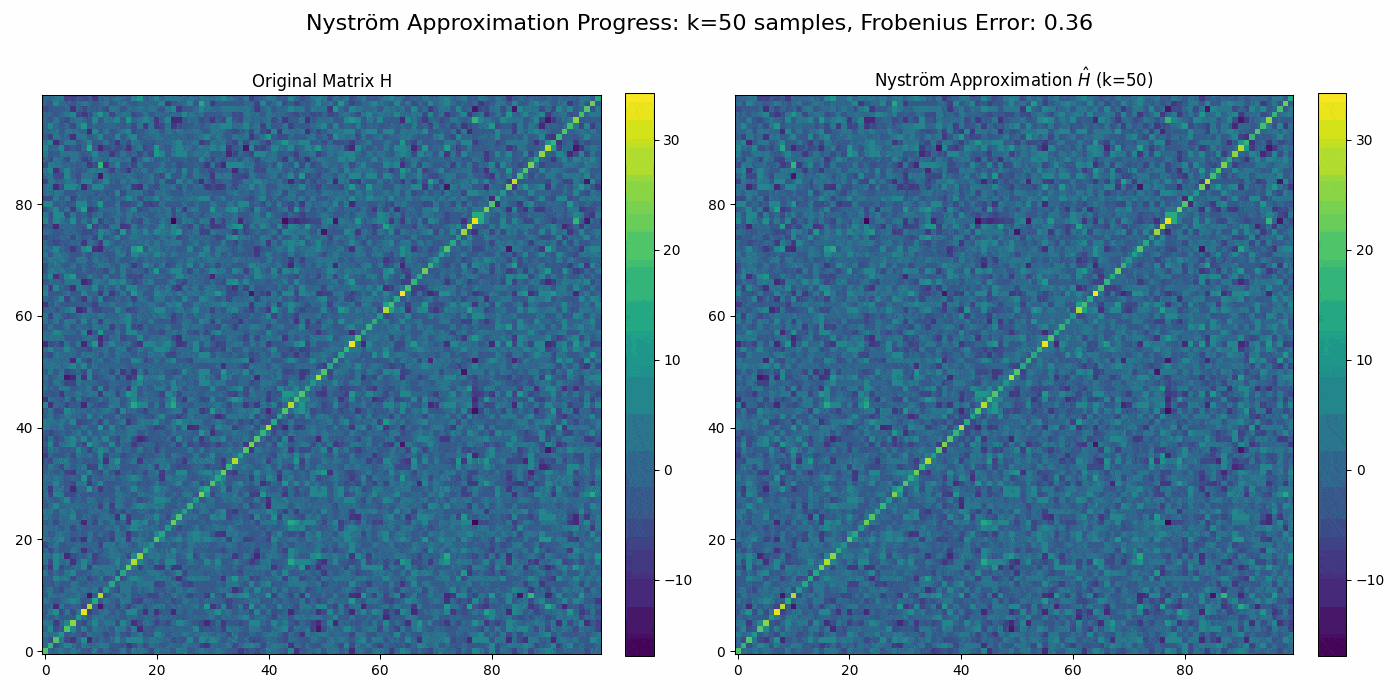 NysReg-Gradient: Regularized Nyström-Gradient for Large-Scale Unconstrained Optimization and its ApplicationIn IEEE International Joint Conference on Neural Networks (IJCNN), IEEE World Congress on Computational Intelligence (WCCI), 2026We develop a regularized Nystrom method for solving unconstrained optimization problems with high-dimensional feature spaces. The method leverages actual Hessian information through a regularized Nystrom approximation, integrating the approximated Hessian with gradient descent and stochastic gradient descent. We establish global convergence and analyse the global complexity. Numerical experiments show that it notably outperforms randomized subspace Newton and the approximation of Newton-sketch, showing considerable advancement in optimization with high-dimensional feature spaces.
- IJCNNNys-Fed: Communication and Memory Efficient Nyström Approximated Curvature for Federated LearningIn IEEE International Joint Conference on Neural Networks (IJCNN), IEEE World Congress on Computational Intelligence (WCCI), 2026
Preprints
- PreprintRegularized Nyström Method for Large-Scale Unconstrained Non-Convex Optimization2024We propose a quasi-Newton type regularized Nystrom method for solving unconstrained large-scale non-convex optimization problems with high-dimensional feature spaces, focusing on l2-regularized objectives. The Hessian of a non-convex function may have negative eigenvalues; we address this by incorporating a regularization parameter to obtain a positive definite matrix and a descent direction, giving a regularized fixed-rank Nystrom approximation whose rank is selectable through random column sampling. We establish global convergence under standard assumptions and provide an analysis of the global complexity.
- arXivNys-curve: Nyström-approximated curvature for stochastic optimization2021We propose an approximate Newton step-based stochastic optimization algorithm for large-scale empirical risk minimization of convex functions with linear convergence rates. We compute a partial column Hessian of size (d x k) with k < d randomly selected variables, then use the Nystrom method to better approximate the full Hessian matrix. To further reduce computational complexity per iteration, we directly compute the update step without computing and storing the full Hessian or its inverse. We also use distribution-preserving sub-sampling to compute a partial Hessian, and integrate the approximation with stochastic gradient descent and stochastic variance-reduced gradients.
Theses
- PhD Thesis
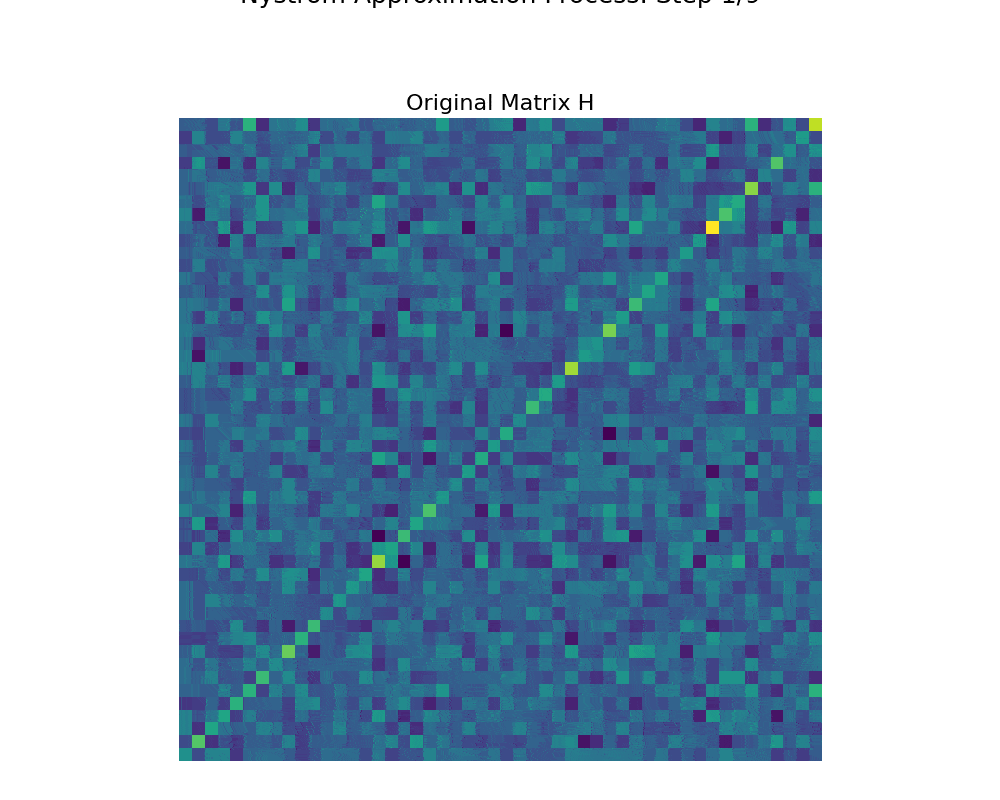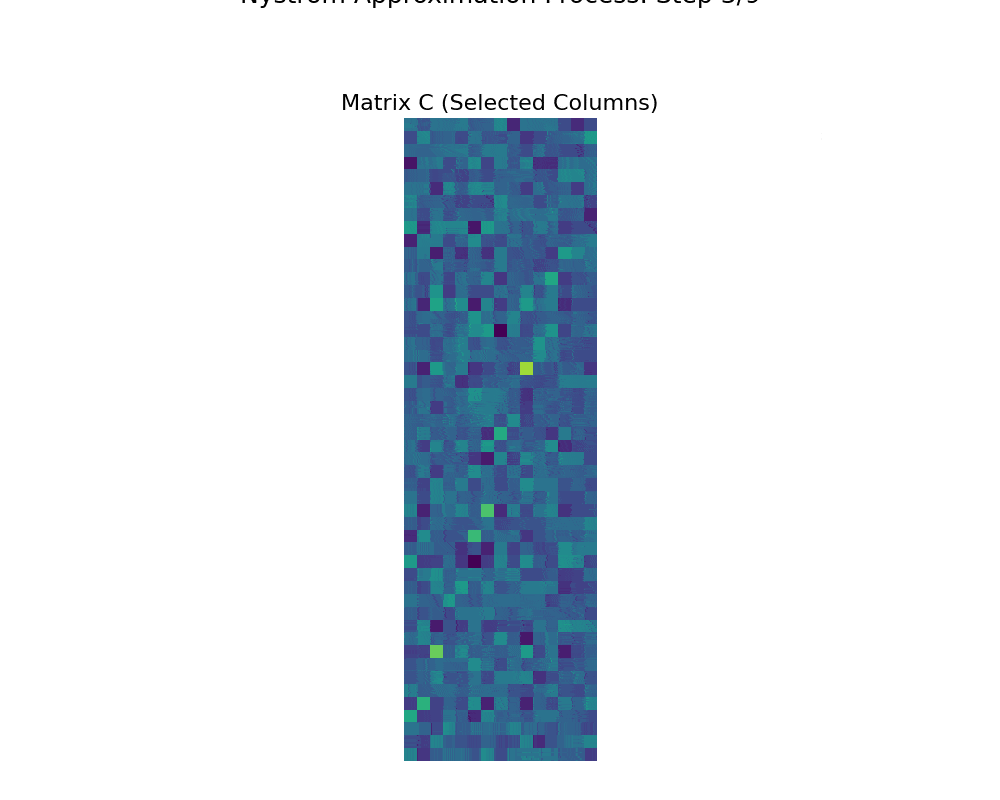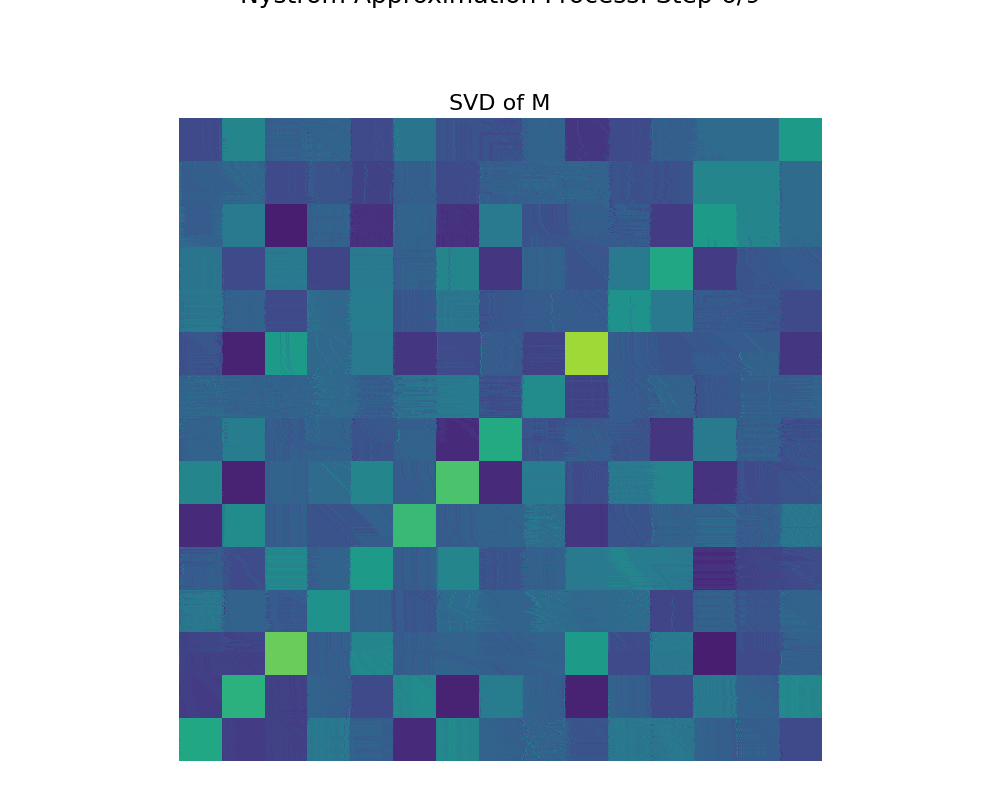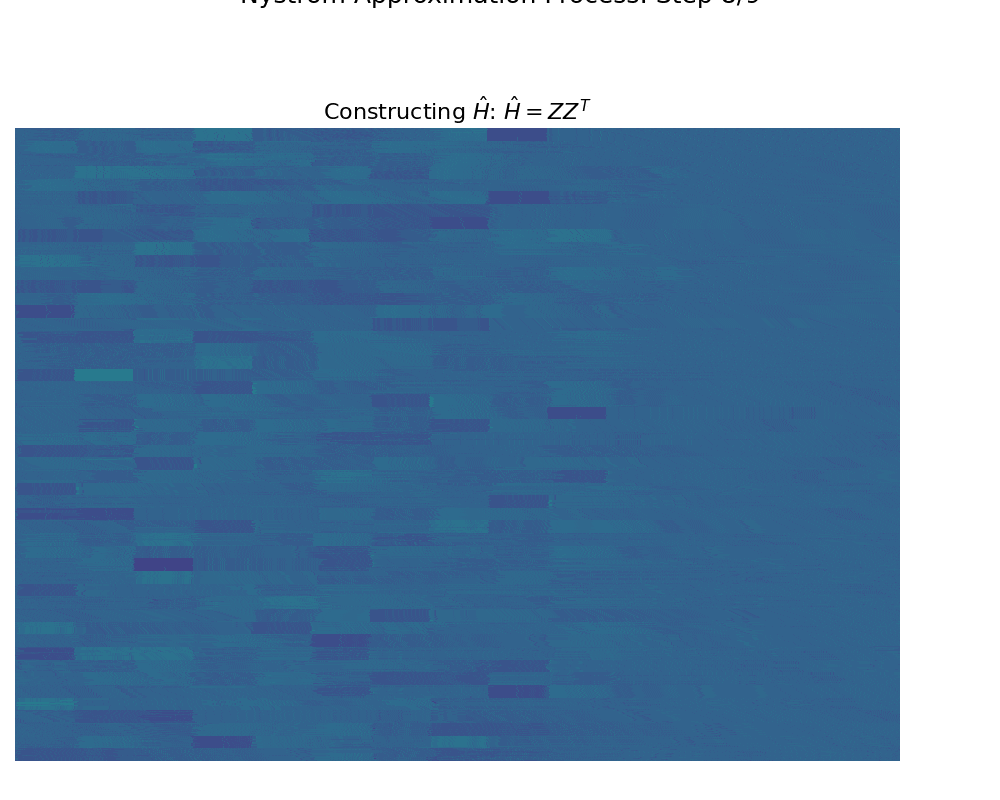 The Utilization of Second-Order Information for Large-Scale Unconstrained Optimization ProblemsKyoto University, Graduate School of Informatics, Mar 2024Doctoral thesis. Second-order and variance-reduced methods for large-scale unconstrained optimization: a regularized L-BFGS method with global convergence and fewer function evaluations; a stochastic variance reduced gradient using Barzilai-Borwein curvature as second-order information; and the regularized Nystrom approximation of the Hessian, which reduces per-iteration cost from O(nd^2 + d^3) to O(ndm + dm^2) with a sketch of roughly 5 to 20 percent of the feature dimension while keeping the step a descent direction on non-convex objectives. Department of Applied Mathematics and Physics, Kyoto University.